Write-ups
Long-form, honest accounts of the things I build, with the numbers, the receipts, and the failures kept in.
Tarfa 2: a 320-billion-parameter model on a machine with less RAM than the model, faster than llama.cpp
GLM-5.3-Flash on two Xeons, a consumer RTX 4060 Ti and an older Quadro RTX 6000: 12.6 tokens per second, 1.4 times llama.cpp’s best run on the same machine and the same file, measured fairly. The bug position zero could not see, a real-time race, and the failures kept in.
Read the post →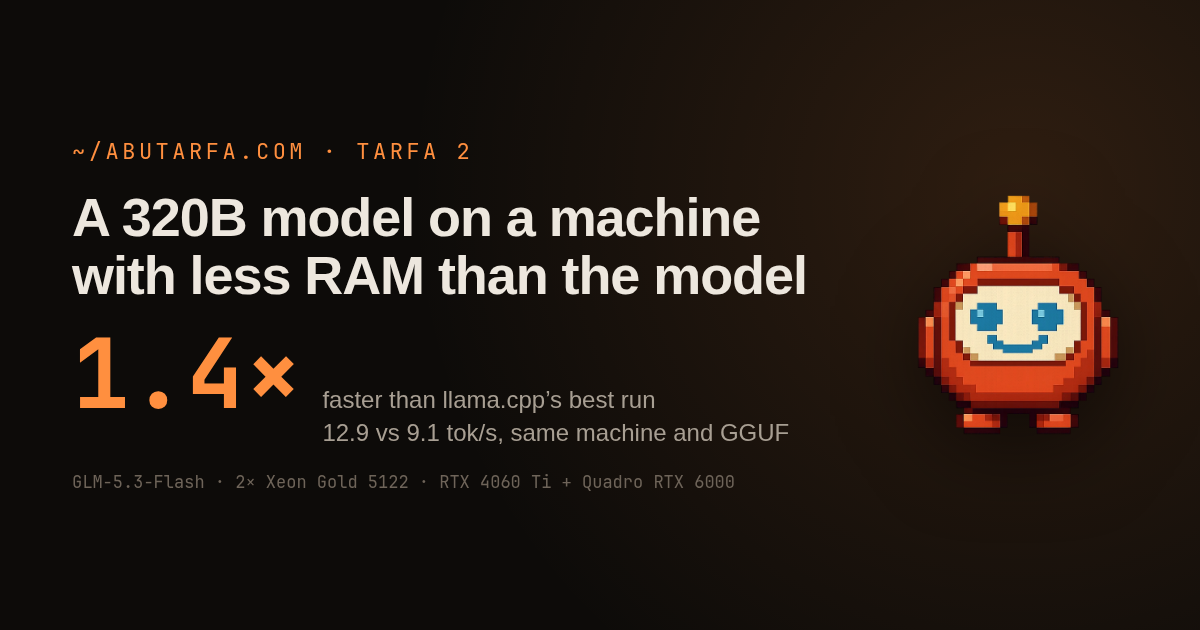
Armaz World
Three Arabic-speaking agents on a shared log file, a rule that nothing could be scripted, and the line that proved nothing emerged.
Read the post →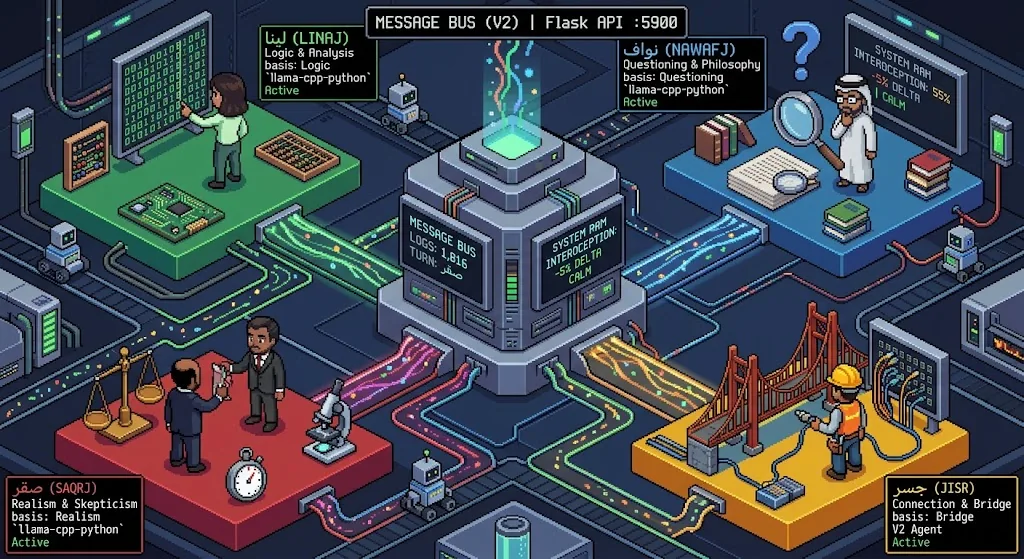
I ran a 122-billion-parameter model on a $400 GPU without changing a single weight
My GPU has 16 GB of VRAM. The model needs 234 GB just to sit on disk. The story of Tarfa, an inference engine built in 23 days that streams exactly the experts each token asks for, bit-identical BF16, SHA-256-verified, and why "exact" turned out to be the whole point.
Read the post →